P사진저렴
Pufy
Fast Image
텍스트로 이미지 생성
Our own fast text-to-image renderer: a 0.5K JPEG draft in seconds, at the lowest price in the catalog. Text in, picture out, no reference images or prompt enhancement.
최소€0.01렌더링당자세히 →
주요 연구소의 이미지, 영상, 3D, 음성, 오디오 모델. 가격을 비교하고 하나의 잔액으로 어떤 모델이든 사용해 보세요.
Our own fast text-to-image renderer: a 0.5K JPEG draft in seconds, at the lowest price in the catalog. Text in, picture out, no reference images or prompt enhancement.
Gemini Omni 1.2 Flash Text-to-Video creates short videos with synchronized audio from a text prompt.
Gemini Omni 1.2 Flash Image-to-Video animates an input image into a short video with audio.
Gemini Omni 1.2 Flash Reference-to-Video creates synchronized audiovisual clips from a prompt and optional image or video references.
Gemini Omni 1.2 Flash Video Edit applies natural-language edits to an existing video.
OpenAI's GPT Image 2.6 Flare Text-to-Image generates high-quality images from natural-language prompts, with five quality tiers up to 4K and a complexity control. Flare is the fast GPT Image 2.6 tier, returning images in seconds for everyday generation and quick iteration.
OpenAI's GPT Image 2.6 Flare Edit edits one or more reference images from natural-language instructions, with five quality tiers up to 4K and a complexity control. Flare is the fast GPT Image 2.6 tier, returning images in seconds for everyday generation and quick iteration.
OpenAI's GPT Image 2.6 Sunburst Text-to-Image generates high-quality images from natural-language prompts, with five quality tiers up to 4K and a complexity control.
OpenAI's GPT Image 2.6 Sunburst Edit edits one or more reference images from natural-language instructions, with five quality tiers up to 4K and a complexity control.
Google Nano Banana 2.1 Edit is the latest Nano Banana image editing model, with gains in visual design, subject consistency and prompt adherence, up to 14 reference images and 1K to 4K output.
Google's Nano Banana 2.1 is the latest Nano Banana text-to-image model, with gains in visual design, subject consistency and prompt adherence, 1K to 4K output and optional web search grounding.
OpenAI's GPT Image 2.5 Flare Edit edits one or more reference images from natural-language instructions, with five quality tiers up to 4K. Flare is the fast, balanced GPT Image 2.5 tier for everyday generation at low latency.
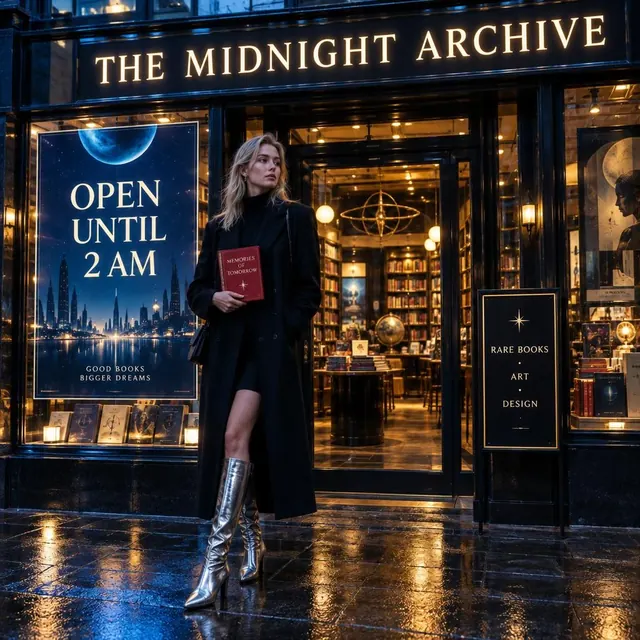
OpenAI's GPT Image 2.5 Flare Text-to-Image generates high-quality images from natural-language prompts, with five quality tiers up to 4K. Flare is the fast, balanced GPT Image 2.5 tier for everyday generation at low latency.
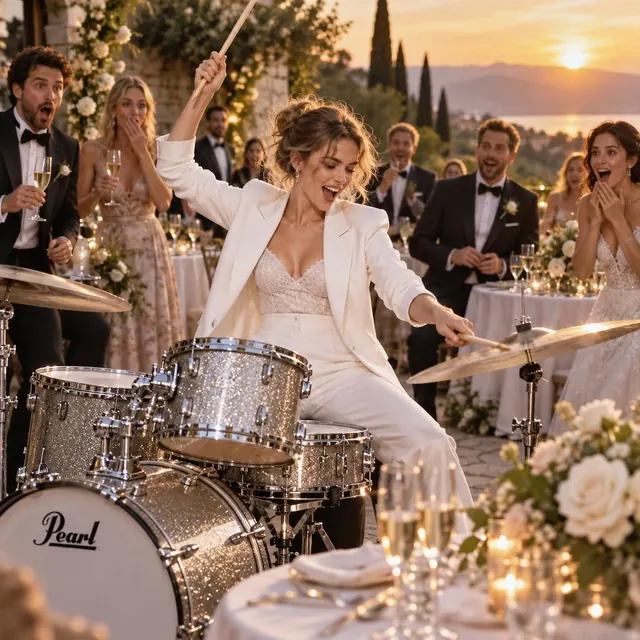
OpenAI's GPT Image 2.5 Sunburst Text-to-Image generates high-quality images from natural-language prompts, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail.
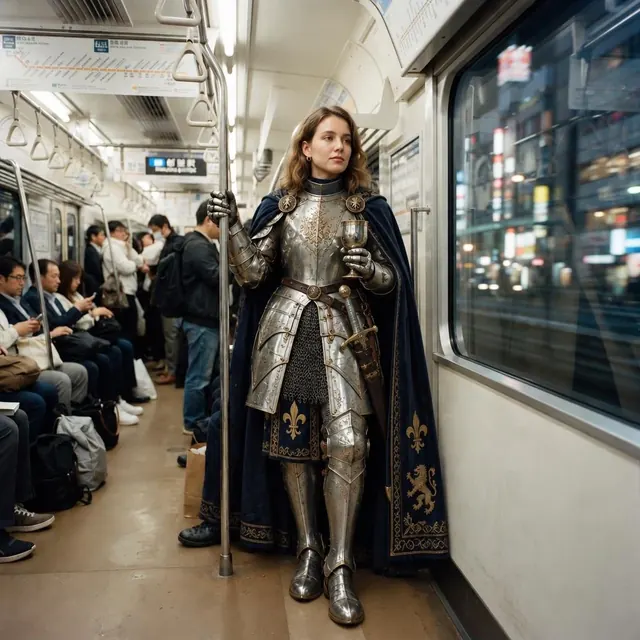
OpenAI's GPT Image 2.5 Sunburst Edit edits one or more reference images from natural-language instructions, with five quality tiers up to 4K. Sunburst is the precision-focused GPT Image 2.5 tier that spends more time per image for extra fidelity on intricate detail.
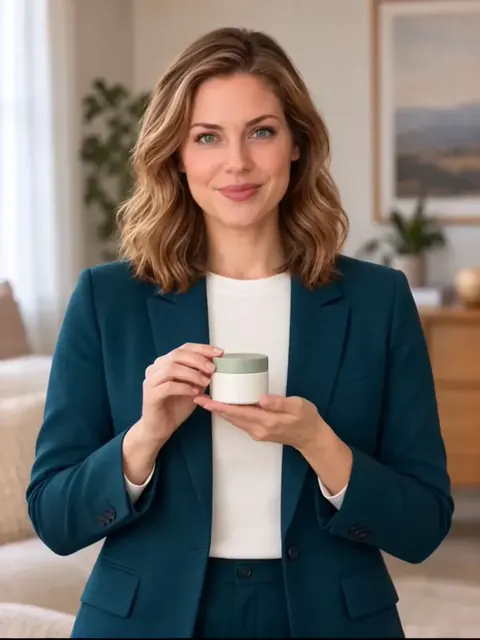
Animate a portrait image from an audio recording with Seedance 2.5. Generate talking-avatar videos in 480p or 720p, processing up to the first 120 seconds of audio.
Seedance 2.5 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability.
Transfer the motion of a reference video onto a character with Seedance 2.5. Your character, from a picture or a short description, performs the same movements, gestures and camera motion as the video, in 480p, 720p or 1080p for up to 30 seconds.
Seedance 2.5 (Video-Edit) edits an input video from a natural-language prompt. The reference video drives subject identity, composition, and motion while the model rewrites lighting, style, weather, environment, or specific elements as instructed.
Seedance 2.5 (Video-Edit Turbo) is the turbo tier for editing an input video from a natural-language prompt - faster, more affordable high-resolution output while preserving subject identity, composition, and motion.
Seedance 2.5 (Video-Extend) extends an input video with a new cinematic continuation generated from its last frame and a natural-language prompt.
Seedance 2.5 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability.
Seedance 2.5 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability.
Wan 3.0 Prime Video-Edit edits an input video using a text prompt and optional reference images and audio. Inputs longer than 15 seconds are trimmed to the first 15 seconds. Output aspect ratio is explicitly selected from the input display dimensions automatically.
Wan 3.0 Prime Video Extend continues a video from its final frame and appends a newly generated 2-30 second segment. Inputs longer than 120 seconds retain their last 120 seconds. Supports 480p, 720p, and 1080p output.
Alibaba WAN 3.0 Prime Reference-to-Video combines reference images, videos, and audio with prompts to create coherent videos with flexible 2-30 second duration, resolution, aspect ratio, audio, and deep-thinking controls.
Alibaba WAN 3.0 Prime Text-to-Video generates videos from text prompts with flexible 2-30 second duration, resolution, aspect ratio, audio, and deep-thinking controls.
Alibaba WAN 3.0 Prime Spicy Image-to-Video converts a first-frame image into a video with optional last-frame guidance, flexible 2-30 second duration, resolution, aspect ratio, audio, and deep-thinking controls.
Alibaba WAN 3.0 Prime Image-to-Video converts a first-frame image into a video with optional last-frame guidance, flexible 2-30 second duration, resolution, aspect ratio, audio, and deep-thinking controls.
Wan 3.0 Video-Edit edits an input video using a text prompt and optional reference images and audio. Inputs longer than 15 seconds are trimmed to the first 15 seconds. Output aspect ratio is explicitly selected from the input display dimensions automatically.
Wan 3.0 Video Extend continues a video from its final frame and appends a newly generated 2-30 second segment. Inputs longer than 120 seconds retain their last 120 seconds. Supports 480p, 720p, and 1080p output.
Alibaba WAN 3.0 Spicy Image-to-Video converts a first-frame image into a video with optional last-frame guidance, flexible 2-30 second duration, resolution, aspect ratio, audio, and deep-thinking controls.
Alibaba WAN 3.0 Text-to-Video generates videos from text prompts with flexible 2-30 second duration, resolution, aspect ratio, audio, and deep-thinking controls.
Seedance 2.5 Spicy (Image-to-Video) generates unlimited high-quality cinematic clips from a reference image and prompt, optimized for scalable content generation with smooth animations and stable aesthetics.
Alibaba WAN 3.0 Image-to-Video converts a first-frame image into a video with optional last-frame guidance, flexible 2-30 second duration, resolution, aspect ratio, audio, and deep-thinking controls.
Alibaba WAN 3.0 Reference-to-Video combines reference images, videos, and audio with prompts to create coherent videos with flexible 2-30 second duration, resolution, aspect ratio, audio, and deep-thinking controls.
Seedance 2.5 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images and text prompts - a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability.
Seedance 2.5 (Text-to-Video Turbo) generates cinematic videos from text prompts at 720p and 1080p with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability - optimized for turbo output.
Seedance 2.5 (Text-to-Video Turbo) generates cinematic videos from text prompts at 720p and 1080p with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability - optimized for turbo output.
Kling V4.0 Reference-to-Video builds a new clip of 3 to 30 seconds from up to 10 reference images, 5 reference videos and 3 reference audios, following the subjects, motion and camera you point to in the prompt, with 720p and 1080p output and synchronized stereo audio.
Kling V4.0 Image-to-Video animates a first frame into a clip of 3 to 30 seconds, with an optional last frame and up to 8 in-between keyframes to direct the story, 720p and 1080p output and synchronized stereo audio.
Kling V4.0 Video Edit rewrites a 3 to 30 second video from a text instruction: it keeps the scene, subject and motion and changes what you describe, with optional reference images and audios, 720p and 1080p output and new synchronized audio generated by default (the original sound can be kept…
Kling V4.0 Video Extend continues a video from its last frame with a new 3 to 30 second segment guided by your prompt, at 720p or 1080p with synchronized stereo audio, and returns the original and the new segment joined.
Kling V4.0 Text-to-Video generates cinematic clips of 3 to 30 seconds from a text prompt, with 720p and 1080p output, four aspect ratios including 21:9 ultrawide, and synchronized stereo audio.
Kling V4.0 Flash Text-to-Video generates 3 to 20 second 720p clips from a text prompt with synchronized audio, in four aspect ratios including 21:9 ultrawide; Flash is the fast, lower-cost tier of Kling 4.0 for quick iteration.
Kling V4.0 Flash Image-to-Video animates a first-frame image into a 3 to 20 second 720p clip with synchronized audio; Flash is the fast, lower-cost tier of Kling 4.0 for quick iteration.
Kling V4.0 Flash Reference-to-Video generates a 3 to 20 second 720p clip guided by up to 10 reference images and 5 reference videos, with synchronized audio; Flash is the fast, lower-cost tier of Kling 4.0.
Kling V4.0 Flash Video Edit rewrites a 3 to 20 second video from a text instruction at 720p: it keeps the scene, subject and motion and changes what you describe, with optional reference images and new synchronized audio by default.
Seedream 5.5 Edit by ByteDance edits and generates images from single-image or multi-reference inputs, supporting up to 10 reference images, consistent multi-turn edits, native transparent-background output, and 1K, 1.5K, 2K and 3K output tiers.
Seedream 5.0 Pro API Preview Edit is ByteDance's advanced image editing model for single-image and multi-reference image generation.
Seedream 5.5 Text to Image by ByteDance generates images from text prompts with improved photographic realism and aesthetics, native transparent-background output, aspect ratio selection, and 1K, 1.5K, 2K and 3K output tiers.
Seedream 5.0 Pro API Preview is ByteDance's advanced image generation model for text-to-image and reference-image generation.
Seedream 5.0 Flash Edit is ByteDance's fast, lower-cost image editing model for single-image and multi-reference image generation.
Seedream 5.0 Flash is ByteDance's fast, lower-cost image generation model for text-to-image generation.
Transform an input image into a short video with xAI Grok Imagine Video v1.5.
Generate a short video from a text prompt with xAI Grok Imagine Video v1.5.
Generate a short video from up to seven reference images with xAI Grok Imagine Video v1.5.
Qwen Image 3.0 edit model with high-quality image editing and advanced instruction understanding.
Qwen Image 3.0 text-to-image model with high-quality image generation and advanced prompt understanding.
Qwen Image 3.0 Pro edit model with professional-grade editing quality and advanced instruction understanding.
가격은 렌더링당 책정되며 렌더링이 성공한 경우에만 잔액에서 차감됩니다. 실패한 렌더링은 자동으로 환불됩니다. 생성 전에 정확한 가격이 표시됩니다.